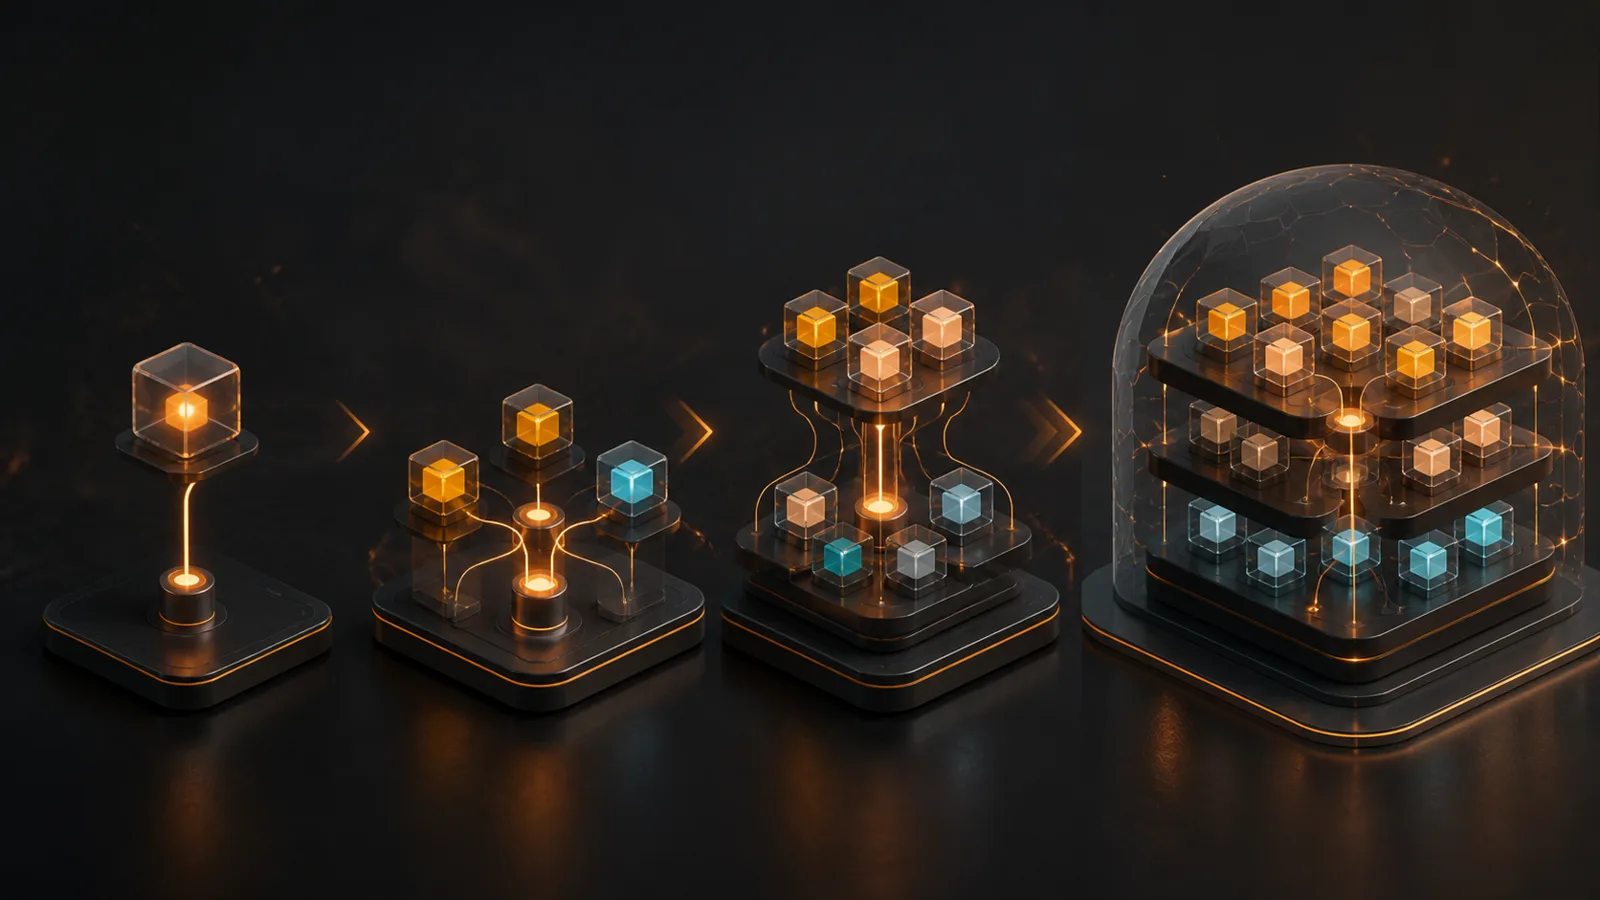
Stage one: stabilize the boundary
Move base URL, credential, model ID, timeout, and retries into one client wrapper and deployment configuration. Preserve the current behavior and add request identifiers. The goal is reversibility, not a new routing algorithm.
Document provider-specific fields before they become hidden dependencies.
Stage two: observe the baseline
Measure request volume, errors, first-token and total latency, tokens or media units, cost, retries, and task outcome by workload. Without a baseline, the team cannot prove that a migration or second model helped.
Allocate usage to projects, environments, and features early.
Stage three: evaluate one substitute
Choose a high-volume or reliability-sensitive workload, build a representative evaluation set, and test one alternate route. Compare quality, schema reliability, latency, and cost per successful task.
Configure same-model provider failover where possible before cross-model fallback. It changes less at once.
Stage four: turn evidence into policy
Externalize model eligibility, preferred order, timeouts, fallback, and budgets. Canary each change and keep rollback in configuration. Add roles, allowlists, and audit as more teams share the platform.
Stop when the current stage solves the real problem. Multi-model flexibility should reduce complexity for the application, not create infrastructure theater.