Typed client for chat, images, video and audio, with routing, fallbacks, metadata and estimated cost as real arguments. Zero dependencies, built on fetch.
One surface, offered as a synchronous and an asynchronous client over the same implementation, so a streamed completion behaves identically in both. One dependency, httpx.
The multimodal surface and the per-request cost figure in one place inside a Flutter app, instead of hand-rolled JSON in a widget. One dependency, package:http.
Pulls OpenAI's or Anthropic's own cost report, compares it against a usage export you already have, and prints the per-day variance. No INFRO account, no signup, no config file.
Run it on your own provider account, or through a gateway key and its policy. See who served it, how long it took, what your provider will bill and the full trace, then copy it as cURL, Python or TypeScript.
A request with feature support-triage reaches the route named support. Its first rule, long-prompts, sends prompts estimated above 32,000 input tokens to a Vertex AI connection and does not match. Its second, support-triage, matches and sends the request to an Anthropic connection, then an AWS Bedrock connection. Anthropic answers 429, the route's failure rule for rate_limit says failover, and the Bedrock connection serves it: the response names the route, the chain position standby_a and the provider.
POST/v1/chat/completionsRoute rules and failover
Request
Where is the refund for order 4821?
feature "support-triage"input_tokens ≈ 1,900
Route supportrules, in order
long-promptsif input_tokens gt 32000 → vertex-prodno match
Five requests go through INFRO's one API: text to Anthropic, an image to OpenAI at resolution 2K and aspect ratio 16:9, a video to Runway at 1080p, the same video at 720p, and speech to ElevenLabs in mp3. INFRO checks every setting against what the model takes on that provider before calling it. The 1080p video is refused at INFRO and never sent to Runway, with the message: Runway Gen-4 Turbo on Runway renders at 720p, not 1080p. At 720p it becomes a job, reported by a signed webhook when it finishes.
Every request is recorded with its route, the connection that served it, each attempt, latency, tokens and an estimate of what your provider will bill — grouped by project, key, model or connection.
Two views play in turn. First, a project's daily estimated provider spend runs near its usual $410 and is projected at $1,240 today; three findings follow: a model answered by a new snapshot with its estimated weekly impact, the unusual spend, and OpenAI's own cost report differing from INFRO's estimates. Second, the project's month-to-date spend is forecast at $5,820 against a $5,000 budget; the findings are output tokens per request rising on a model, the forecast over budget, and Anthropic's cost report differing from the estimates. The reconciliation findings are marked with the plan that includes them.
GET/v1/alertsFindings, also in the console
Daily spend · project support-assistantUsual day $410Projected today $1,240
traffic.model_changedopenai/gpt-5.6-terra is answered by a new model snapshot: gpt-5.6-terra-2026-10-02Before gpt-5.6-terra-2026-08-14+$212.40Estimated weekly impact
spend.anomalyUnusual spend: project support-assistant on course for $1,240 todayUsual day $410$1,240Projected today
cost.driftBusinessCost estimates for openai are 8.4% below what the provider reportedSource OpenAI cost API6 of 7Days drifting
Two gateway keys and their policy. The production key belongs to the project support-assistant, may use Anthropic and AWS Bedrock from one IP range, and the project allows one model under a blocking budget. Its requests are decided one at a time before any provider is called: an allowed model is served by the Anthropic connection, a model outside the allowlist is refused 403 model_not_allowed, a request from another address is refused 403 ip_not_allowed, and a request past the project budget is refused 402 budget_exceeded with code project_budget. The staging key cannot reach a connection scoped to production and is refused 503 connection_out_of_scope; a model served by a staging connection goes through.
POST/v1/chat/completionsChecked before the provider
support-prodproject support-assistantenvironmentproductionprovidersanthropic, aws-bedrockIP ranges10.20.0.0/16modelsanthropic/claude-sonnet-5.5budget$5,000 a month, blocks
A cap for every person, and for every customer of yours.
Cap each member’s estimated provider spend for the month, and choose whether reaching it alerts or blocks.
Every key they create counts toward one cap.
Block or alert, set per person.
The strictest policy wins across org, project and key.
Team budgets
This month · estimated provider spend
Team spend
$245 of $450
Remaining
$205
Team members and their monthly caps on estimated provider spend this month
Person
Monthly capA monthly cap on estimated provider spend, across every gateway key this member created. Organization, project and key policies can also apply, and the strictest one wins.
This month
Remaining
Maya ChenMember · 2 keys
Monthly capBlocks at cap
This month$120 of $20060%
Remaining$80
Omar AliMember · 1 key
Monthly capBlocks at cap
This month$80 of $10080%Nearing cap
Remaining$20
Lena BrooksAdmin · 1 key
Monthly capAlert only
This month$45 of $15030%
Remaining$105
Your customers
Cap what each of your own customers can spend per day, week or month. Send their id with the request; when they reach the cap, the gateway answers 402 with the time it resets, so your app can tell them. From the Team plan.
Three of your customers, each with a daily cap of 2 dollars of estimated provider spend. Their requests are served and each customer's meter fills. A request that would take cus_4f2a past the cap is refused with 402 before it reaches your provider, and the response says when the cap resets: 00:00 UTC. At midnight UTC every daily cap resets.
cus_7a2c+$0.60$0.00$0.60
cus_91be+$0.40$0.00$0.40
cus_4f2a+$0.90+$0.80$0.00$0.90$1.70
Under the cap: served402cus_4f2aCap reached · resets at 00:00 UTC00:00 UTC · every daily cap resets
Everymodelyoupayfor,inonestudio.
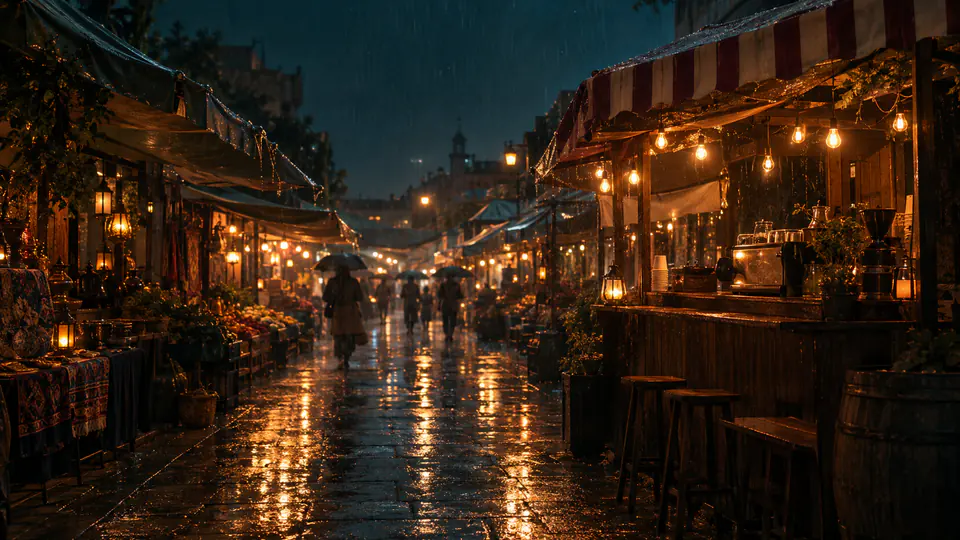
Images, video and sound on the providers you already pay, from the first prompt to the cut your editor opens.
1AThe market in the rainArrival1BMara under the awningArrival1CLanterns, closeArrival2AThe cupThe stall2BKen poursThe stall2CRain on the windowThe stall3AUnder one umbrellaTogether3BThe alley upTogether3CDawn, end cardTogether
An example project, Night market: a 30-second spot of 9 shots. Each keyframe was made with GPT Image 2 and animated on a video model, with voice, effects and music on the audio models of the organization's own providers.
Running 3est. $2.23 in flight
Mara and Ken share one umbrella down the wet market lane, s…GPT Image 2 · OpenAI · est. $1.84
warm lo-fi piano, light rain, hopefulEleven Music · ElevenLabs · est. $0.07
Video upscaleTopaz Video Upscale · Replicate · est. $0.32
2B Voice lineest. <$0.01
Ken“Last cup of the night.”ElevenLabs V4 · ElevenLabs
1B Mara under the awning4 takes
Kling O3fal · 4 s · $0.45 Kept
Veo 3.1Google · 4 s · $1.60
Seedance 2.0Replicate · 4 s · $0.60
Runway Gen-4.5Runway · 4 s · $0.48
Kling O3 kept
PictureVoiceEffectsMusic
0s51015202530
MaraKenElevenLabs V4
ElevenLabs Sound Effects v2
Eleven Music · warm lo-fi piano, light rain, hopeful
Three prompts arrive on a route. For each one the decision model answers a choice question, how much reasoning the request needs, with a probability for small, medium and large. INFRO's route rules send the request to the model for the most likely class, and the response names the class in the X-INFRO-Route-Class header. Answered here by GPT-6 Luna (Decisions) from OpenAI.
Prompt
What’s your refund window?
GPT-6 LunaOpenAIchoice
How much reasoning does this request need?
small0.86Gemini 3.8 Flash
medium0.11Claude Sonnet 5.5
large0.03Claude Opus 5.5
Waiting for the response200X-INFRO-Route-Classsmall; confidence=0.79; source=modelmodelgoogle/gemini-3.8-flash
01Your provider accountsEvery decision runs on your own connection, billed by your provider.
02Inside your budgetsChecked against key scope and spend limits before the call.
03Recorded with its costEach call is a row in the request log: model, answer, estimated cost.
INFRO is an AI gateway and control plane: one API between your applications and the AI providers you already pay, such as OpenAI, Anthropic and Google. You connect your own provider accounts and keep your contracts and rates; INFRO routes each request, fails over when a provider errors, checks budgets before the call, records the latency and estimated cost of every request, and applies policy on keys, models and data. Engineering teams use it for one integration across text, image, video and audio; finance teams for spend by team, project and customer; platform and security teams for central control of provider keys and model access. Your providers bill you for model usage directly, at your rates; INFRO charges a monthly subscription for the software, with 0% markup on model spend.
Why use INFRO instead of calling OpenAI or Anthropic directly?
If you use one model from one vendor and nobody has asked what it costs, you probably should go direct — that is a real answer and we would rather give it than waste your evaluation. INFRO earns its place when at least one of these is true: you run several models across several vendors, a provider incident has taken your product down, someone has started asking which customer or feature is spending what, or provider keys have started appearing in more than one place. You still call the same providers on the same accounts; you stop owning the integration, the failover and the accounting between them.
How does the trial start?
Create an account at dash.infro.io and verify your email address. You create your organization, choose a plan and add a card at checkout, and your 14-day trial starts when that checkout completes. At the end of day 14 the plan you have selected is charged automatically — cancel before day 14 and you won't be charged. Your providers keep billing you directly for model usage throughout.
Can I run TypeSafe's Jev through INFRO?
Yes. INFRO serves TypeSafe's POST /v1/systemone with TypeSafe's request body and model names, so TypeSafe's SDK works against INFRO with a new base URL and an INFRO gateway key. Each decision runs on your own TypeSafe account and TypeSafe bills you for it directly. Before TypeSafe is called, INFRO checks the key and any spend limit; afterwards it returns TypeSafe's answers with the version that answered and an estimated cost, and records the request.
What happens if INFRO itself fails?
We become one more dependency — that is the honest cost of the trade, and you should price it in. Three things make it survivable. The status page runs on a separate, far simpler deployment than the gateway and checks the gateway from your own browser. Text speaks the OpenAI shape, so keeping a direct provider key and a base-URL switch in your config is a two-line contingency we actively recommend. And there is no published uptime SLA, because a service with no operating history cannot honestly offer one; an enterprise agreement can carry a contractual one.
Can I leave later?
Yes, and the migration back is the same two lines that brought you in. Retrieve request and usage history through the public APIs, or download it as CSV from the request log and Analytics, and keep it in your own systems before it leaves your plan's queryable history window. There are no scheduled or emailed exports.
How is our company data handled, and do you train on it?
We never train on your prompts, inputs, or outputs, and we never sell them. Usage metadata supports platform metering, cost estimates and governance. Optional prompt and response logging is off by default and limited by your plan. Job records and generated media needed for delivery are separate. Your AI providers' data-use and retention settings remain governed by your agreements with them.